CUT LLM SPEND BY MOVING EMBEDDINGS LOCAL AND SQUEEZING INFERENCE — NO NEW HARDWARE REQUIRED
Teams are quietly slashing LLM costs by running embeddings on CPU and optimizing inference before buying more GPUs. A dev building a small RAG app realized the...
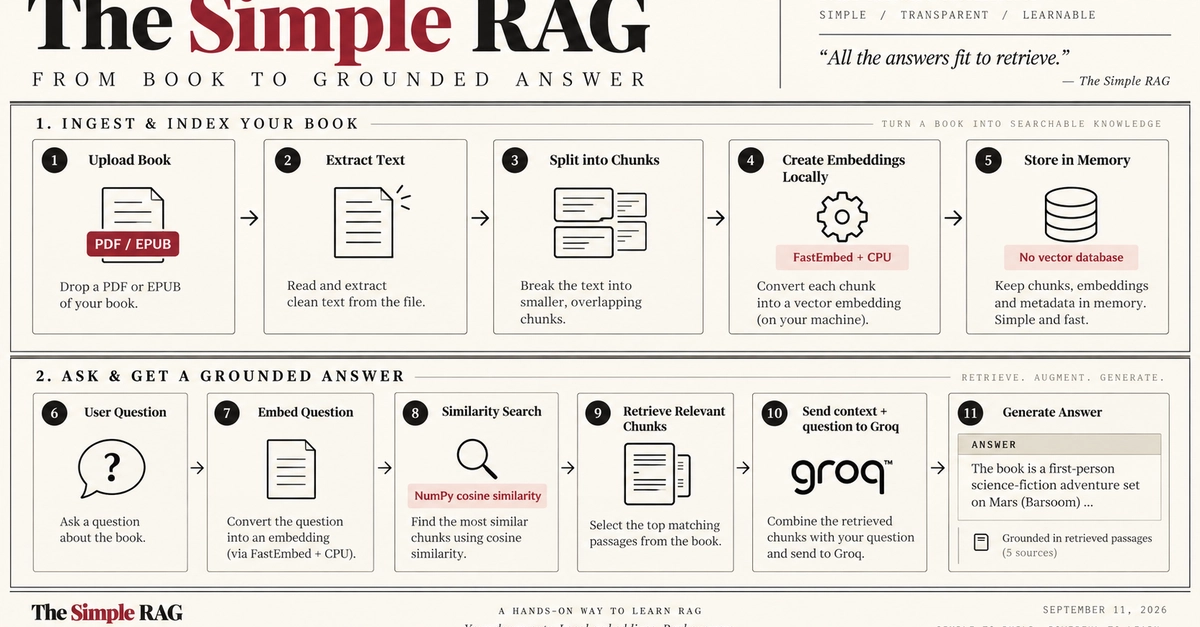
Teams are quietly slashing LLM costs by running embeddings on CPU and optimizing inference before buying more GPUs.
A dev building a small RAG app realized the priciest moving part was paid embedding APIs — then swapped to local embeddings with FastEmbed and a small BGE model on ONNX Runtime, all on CPU, no GPU or PyTorch needed story.
Chip Huyen lays out how to cut inference bills without new boxes — think batching, quantization, distillation, and better request scheduling talk recap. A separate cost check suggests an AMD dual‑GPU rig can beat ChatGPT pricing after a usage crossover, but only once your load is steady enough to keep hardware busy analysis.
Even tokenization choice affects throughput and cost per request; a quick benchmark compares tiktoken, HF Tokenizers, and sentencepiece under real loads bench.
Embedding calls often dominate RAG run-rate; local CPU embeddings remove API bills and rate limits.
Software optimizations can delay or avoid GPU capex if you batch, quantize, and schedule well.
-
terminal
Benchmark local CPU embeddings (FastEmbed + bge-small) vs API for latency, recall, and total cost at your QPS.
-
terminal
Run an A/B on inference with batching + 4/8-bit quantization and measure cost/request and tail latency.
Legacy codebase integration strategies...
- 01.
Swap API embeddings for ONNX Runtime locally with a feature flag; keep an API fallback for spikes.
- 02.
Add caching and background pre-embedding for hot docs to reduce p95 without new infra.
Fresh architecture paradigms...
- 01.
Design local-first embeddings and reserve API calls for rare long-tail cases.
- 02.
Instrument tokenization, batching, and KV-cache hit rates from day one to guide scale-up vs. buy.
Get daily ONNX-RUNTIME + SDLC updates.
- Practical tactics you can ship tomorrow
- Tooling, workflows, and architecture notes
- One short email each weekday